SnapMirror asynchronous DR

Ask any CIO what keeps them awake and “the data centre floods” is near the top of the list. The answer on ONTAP is a copy of every important volume on a second cluster in another city, kept a few minutes or an hour behind production.

That copy is a SnapMirror relationship. With the peering from Lesson 38 in place, you’ll mirror a volume, read its health and lag, run a DR test where the DR copy becomes writable, and put it back into sync afterwards.

Where this lesson fits

Lesson 39 of 56 in NetApp ONTAP Storage Administration · Phase 3: Data protection and integrations · Before this: Lesson 38, cluster and SVM peering · Next: Lesson 40, SnapMirror vault (SnapVault)

TimeYou needBy the end you can
60 minutesThe practice shell with saat-cluster and saat-dr peered (Lesson 38)Create and initialize a mirror, check lag, fail over with quiesce and break, and resync after a DR test

What it is, in one line

SnapMirror asynchronous replication copies a volume to another cluster on a schedule by sending only the blocks that changed since the last common snapshot, so the DR copy is always a recent, read-only point in time.

In Simple Words

A second copy of the ledger in another branch

A shop keeps its account book at the counter. Every evening the owner photocopies only the pages that changed that day and sends them by courier to his brother’s shop in the next town, who files them into an identical book.

If the first shop burns down, the brother’s book is at most one day old. During normal days nobody writes in the brother’s copy; if he ever has to start using it, the two books go different ways until someone copies the latest pages back across.

Engineer's View

How an engineer describes it

The destination is a DP (data protection) volume, read-only while the relationship is active. snapmirror create runs on the destination cluster and names the source and destination as svm:volume, a policy and a schedule. Since ONTAP 9.3 new relationships use the unified XDP engine, so snapmirror show lists the type as XDP even for a plain DR mirror.

snapmirror initialize sends a full baseline. After that each update takes a new SnapMirror snapshot on the source and sends only the blocks changed since the last common snapshot. The MirrorAllSnapshots policy (type async-mirror) keeps the DR copy identical to the source including its snapshots; MirrorAndVault also keeps a longer history, which Lesson 40 covers.

For a failover you quiesce and break on the destination, which makes the DP volume read-write. resync later finds the newest common snapshot and continues from it, throwing away anything written after it on the destination. Watch lag-time and healthy every day: a relationship can sit “Snapmirrored” for weeks while updates quietly fail.

How it works, step by step

1Create a DP volume on DR

Same size or bigger than the source, on an aggregate with room to grow, with -type DP. Turn on autosize so it can follow the source.

2Create and initialize the relationship

Run both on the destination. The baseline can take hours or days over a WAN; seed large volumes during quiet hours.

ONTAP SnapMirror transfer cycle: snapshot, send changed blocks, update the DR copy

3Let the schedule run

Each scheduled update moves the DR copy forward. Your recovery point (RPO) is roughly the schedule plus the time a transfer takes.

4Watch health and lag

Alert when lag is more than twice the schedule. snapmirror show -instance gives the Unhealthy Reason when something fails.

CommandRun it onWhat it does
snapmirror createDestinationDefines source, destination, policy, schedule
snapmirror initializeDestinationBaseline transfer
snapmirror updateDestinationTransfer now, outside the schedule
snapmirror quiesce / breakDestinationStop updates, make the DR volume RW
snapmirror resyncDestination (or the new destination)Put a broken relationship back in sync
snapmirror releaseSourceClean up after deleting a relationship
ONTAP SnapMirror states: uninitialized, snapmirrored, broken-off and back

5Fail over, then come back

In a real disaster you break, mount or map the DR volumes and point clients at the DR SVM. To go home later you reverse the relationship (DR becomes the source), resync, then plan a short failback. After a DR test, a plain resync in the original direction discards the test writes.

In System Manager, Storage › Volumes, select the volume and choose Protect to pick the DR cluster, SVM and policy; it creates the DP volume and initializes for you. Relationships live under Protection › Relationships, where the three-dot menu offers Update, Break, Resync and Reverse resync.

ONTAP SnapMirror relationships list in System Manager with Update, Break and Resync actions
System Manager: SnapMirror relationships with the actions menu open.

Good to know: two things that save time with SnapMirror

SnapMirror sends blocks as they are stored, so deduplication and compression savings travel with the data and are kept on the destination. A volume that is 60 percent smaller on the source doesn’t grow back to full size on the DR side.

snapmirror protect can replace the separate create and initialize steps. One command such as snapmirror protect -path-list svm1:vol1 -destination-vserver svm1dr -policy MirrorAllSnapshots -auto-initialize true creates the destination volume, the relationship and the first transfer, and it can protect several volumes at once.

Hands-on lab: mirror, fail over and resync a volume

Before you run any command, double-check it

Read every command twice before you press Enter. Check the target: the server name, the user, the disk or device name, the path and the sizes. These commands are for learning and were tested in our lab, not on your system. At work, run the read-only commands first, follow your change process, make sure a backup exists, and ask a second person to check anything that changes or deletes data. You run them at your own risk.

This lab uses the SaatVedha ONTAP practice shell, our own learning tool. It is not NetApp software: real ONTAP output looks like this but is not identical.

Start where Lesson 38 ended: saat-cluster and saat-dr peered, svm1 and svm1dr peered. Keep one terminal on each cluster.

1saat-cluster: a volume worth protecting

volume create -vserver svm1 -volume vol_sales -aggregate aggr1_01 -size 100g -junction-path /sales
simctl write svm1 vol_sales 20g db
simctl host linux1 mount 192.168.56.130:/sales /mnt/sales vers=3
simctl host linux1 touch /mnt/sales/q3.csv

✅ Checkpoint: vol_sales exists with 20 GB of data and is mounted on linux1.

2saat-dr: create the DP volume and the relationship

volume create -vserver svm1dr -volume vol_sales_dr -aggregate aggr1_dr -size 100g -type DP
snapmirror create -source-path svm1:vol_sales -destination-path svm1dr:vol_sales_dr -policy MirrorAllSnapshots -schedule hourly
snapmirror show

You should see this:

[Job 109] Job succeeded: Successful
saat-dr::> snapmirror create -source-path svm1:vol_sales -destination-path svm1dr:vol_sales_dr -policy MirrorAllSnapshots -schedule hourly
Operation succeeded: snapmirror create for the relationship with destination "svm1dr:vol_sales_dr".
saat-dr::> snapmirror show
Source            Destination  Mirror  Relationship   Total             Last
Path        Type  Path         State   Status         Progress  Healthy Updated
----------- ---- ------------ ------- -------------- --------- ------- --------
svm1:vol_sales
            XDP  svm1dr:vol_sales_dr
                              Uninitialized
                                      Idle           -         true    -

The relationship exists but no data has moved, so the state is Uninitialized.

✅ Checkpoint: Mirror State is Uninitialized and Type is XDP.

3saat-dr: run the baseline

snapmirror initialize -destination-path svm1dr:vol_sales_dr
simctl tick 2
snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status,healthy,lag-time
volume show -vserver svm1dr -volume vol_sales_dr -fields type,used

You should see this:

Operation is queued: snapmirror initialize of destination "svm1dr:vol_sales_dr".
saat-dr::> simctl tick 2
simctl: time moved forward (2 steps).
saat-dr::> snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status,healthy,lag-time
source-path    destination-path    state        status healthy lag-time
-------------- ------------------- ------------ ------ ------- --------
svm1:vol_sales svm1dr:vol_sales_dr Snapmirrored Idle   true    0:00:00
saat-dr::> volume show -vserver svm1dr -volume vol_sales_dr -fields type,used
vserver volume       type used
------- ------------ ---- -------
svm1dr  vol_sales_dr DP   20.03GB

The 20 GB baseline has arrived, the relationship is Snapmirrored and Idle between updates, and the DR volume is still type DP (read-only). If you run snapmirror show right after initialize, Status says Transferring with a progress figure.

✅ Checkpoint: state Snapmirrored, healthy true, DR volume type DP.

4saat-dr: a DR test, break the mirror

snapmirror quiesce -destination-path svm1dr:vol_sales_dr
snapmirror break -destination-path svm1dr:vol_sales_dr
snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status
volume show -vserver svm1dr -volume vol_sales_dr -fields type

You should see this:

Operation succeeded: snapmirror quiesce for destination "svm1dr:vol_sales_dr".
saat-dr::> snapmirror break -destination-path svm1dr:vol_sales_dr
Operation succeeded: snapmirror break for destination "svm1dr:vol_sales_dr".
saat-dr::> snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status
source-path    destination-path    state      status
-------------- ------------------- ---------- ------
svm1:vol_sales svm1dr:vol_sales_dr Broken-off Idle
saat-dr::> volume show -vserver svm1dr -volume vol_sales_dr -fields type
vserver volume       type
------- ------------ ----
svm1dr  vol_sales_dr RW

The DR volume is now read-write and scheduled updates have stopped. Production is untouched, so a DR test like this is safe as long as you resync afterwards.

✅ Checkpoint: state Broken-off and type RW.

5saat-dr: let a client use the DR copy

volume mount -vserver svm1dr -volume vol_sales_dr -junction-path /sales
network interface create -vserver svm1dr -lif svm1dr_nas1 -service-policy default-data-files -home-node saat-dr-01 -home-port e0c -address 192.168.57.130 -netmask 255.255.255.0
vserver nfs create -vserver svm1dr -v3 enabled -v4.1 enabled
vserver export-policy rule create -vserver svm1dr -policyname default -clientmatch 192.168.56.0/24 -rorule sys -rwrule sys -superuser sys
simctl host linux1 mount 192.168.57.130:/sales /mnt/sales_dr vers=3
simctl host linux1 touch /mnt/sales_dr/dr_test.csv

The mount line should say:

(mounted 192.168.57.130:/sales on /mnt/sales_dr type nfs)

SnapMirror copies the data, not the DR SVM’s network and protocol setup, so a volume-level DR plan must include LIFs, NFS or SMB, export policies and DNS on the DR side. Lesson 41’s SVM DR copies those too.

✅ Checkpoint: linux1 mounted the DR copy and wrote dr_test.csv.

6saat-dr: end the test and resync

volume unmount -vserver svm1dr -volume vol_sales_dr
snapmirror resync -destination-path svm1dr:vol_sales_dr
snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status
volume show -vserver svm1dr -volume vol_sales_dr -fields type

Answer y to the warning. You should see this:

Warning: All data newer than Snapshot copy snapmirror.045ec5f3_2155079742.2026-11-07_065657 on volume svm1dr:vol_sales_dr will be deleted. Do you want to continue? {y|n}: y
Operation is queued: snapmirror resync to destination "svm1dr:vol_sales_dr".
saat-dr::> snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status
source-path    destination-path    state        status
-------------- ------------------- ------------ ------------
svm1:vol_sales svm1dr:vol_sales_dr Snapmirrored Transferring
saat-dr::> volume show -vserver svm1dr -volume vol_sales_dr -fields type
vserver volume       type
------- ------------ ----
svm1dr  vol_sales_dr DP

The warning is the important line: dr_test.csv and anything else written during the test is thrown away, and the volume is DP again. Your snapshot name will differ. In a real failover where users worked at DR for days, you’d reverse the direction instead so their changes flow back to production.

✅ Checkpoint: state Snapmirrored and type DP again.

Practice shell output: ONTAP SnapMirror relationship initialized and healthy
After the baseline transfer the relationship is Snapmirrored, Idle and Healthy, with zero lag.

Break It, Then Fix It

Do this on the healthy relationship from the lab.
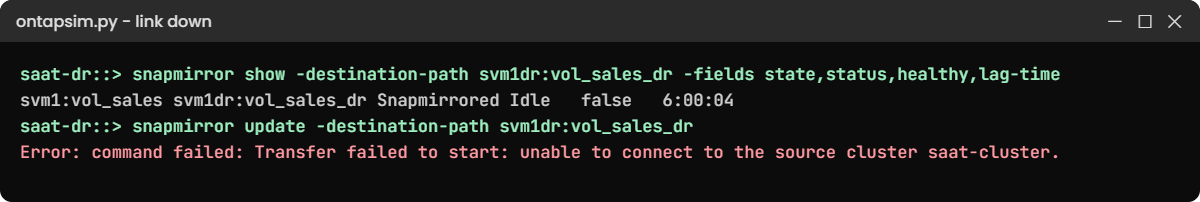
Practice shell output: SnapMirror unhealthy after the WAN link fails
With the link down, scheduled updates fail and the lag keeps growing until someone notices.

1The WAN link goes down

simctl break sm-link-down
simctl tick 3
snapmirror show -destination-path svm1dr:vol_sales_dr -fields state,status,healthy,lag-time
snapmirror update -destination-path svm1dr:vol_sales_dr
snapmirror show -instance

On saat-dr you’ll get this:

source-path    destination-path    state        status healthy lag-time
-------------- ------------------- ------------ ------ ------- --------
svm1:vol_sales svm1dr:vol_sales_dr Snapmirrored Idle   false   6:00:04
saat-dr::> snapmirror update -destination-path svm1dr:vol_sales_dr
Error: command failed: Transfer failed to start: unable to connect to the source cluster saat-cluster.
saat-dr::> snapmirror show -instance
                Source Path: svm1:vol_sales
           Destination Path: svm1dr:vol_sales_dr
          Relationship Type: XDP
        SnapMirror Schedule: hourly
     SnapMirror Policy Type: async-mirror
          SnapMirror Policy: MirrorAllSnapshots
               Mirror State: Snapmirrored
        Relationship Status: Idle
             Total Progress: -
            Newest Snapshot: snapmirror.045ec5f3_2155079742.2026-11-07_065630
                    Healthy: false
           Unhealthy Reason: Scheduled update failed to start. (Transfer failed to connect to the source cluster.)
                   Lag Time: 6:00:04
Last Transfer End Timestamp: 11/7/2026 06:56:30
            Relationship ID: 045ec5f3-22c4-6808-9400-3cc080541a26

Look at the state: still Snapmirrored. Anyone checking only that column thinks DR is fine, while the copy is six hours old and getting older. Healthy false, the lag and the Unhealthy Reason tell the real story; then cluster peer show and network ping -lif from Lesson 38 confirm it’s the network.

Fix the link (here simctl fix sm-link-down), run snapmirror update and check that Healthy goes back to true. On a real system lag drops back below the schedule after the next transfer finishes.

simctl fix sm-link-down
snapmirror update -destination-path svm1dr:vol_sales_dr
simctl tick 1
snapmirror show

✅ Checkpoint: Healthy shows true again.

2Mirror into a normal volume

volume create -vserver svm1dr -volume vol_hr_dr -aggregate aggr1_dr -size 50g
snapmirror create -source-path svm1:vol_sales -destination-path svm1dr:vol_hr_dr -policy MirrorAllSnapshots -schedule hourly

You’ll get this:

Error: command failed: Destination volume "vol_hr_dr" must be of type DP. Create it with "volume create ... -type DP".

ONTAP won’t overwrite a normal read-write volume with a mirror. Delete the wrong volume (it’s empty) and create it again with -type DP, or let System Manager’s Protect wizard create the destination for you.

✅ Checkpoint: You can say why the destination must be DP.

This happened at work

The DR copy that was three days old

A hospital group in Thane ran its yearly DR drill on a Saturday morning. The plan was simple: break the SnapMirror relationships for the patient records system, bring the application up at the DR site and check a few records.

The application came up, but the latest admissions were missing. The DR copy was from Wednesday. A firewall change on Wednesday night had dropped traffic between the intercluster subnets, and every hourly update since then had failed, while the dashboard the team watched only showed Mirror State, which still said Snapmirrored.

Nothing was lost, because production was fine, but the drill would have meant losing three days of records in a real disaster. The team added a daily alert on healthy false and on lag over two hours, and the network team now copies the storage team on every rule change that touches the replication subnets.

Common mistakes and troubleshooting

MistakeWhat happensDo this instead
Watching only Mirror StateA relationship stays Snapmirrored while updates fail for daysAlert on healthy false and on lag-time over twice the schedule
Running snapmirror create on the sourceThe command fails or creates nothing usefulCreate, initialize, update, break and resync on the destination
DR volume smaller than the sourceTransfers fail as the source growsMake it the same size or larger, with autosize on
Plain resync after a real failoverDays of work done at DR are thrown awayReverse the relationship so DR changes go back to production
No DR network or protocol setupVolumes are ready but no client can reach themPre-build LIFs, NFS/SMB, exports and DNS on the DR SVM, or use SVM DR

Interview questions

Click a question to open it. Each one is written the way an interviewer would ask it. Under it you will see why they ask it and one way you could answer, in your own words.

Fresher level

1. What is SnapMirror, in simple words?

Why they ask this: They want to hear that you know it’s block-level, snapshot-based replication to another cluster.

How you might answer: It replicates a volume to another ONTAP cluster. After a full baseline, each update sends only the blocks that changed since the last common snapshot, so the DR copy is a recent read-only point in time that I can make writable in a disaster.

2. Which cluster do you run snapmirror create and initialize on?

Why they ask this: They’re checking practical knowledge that trips up beginners.

How you might answer: On the destination cluster. I create a DP volume there, then run snapmirror create and snapmirror initialize with the source and destination paths. Break, update and resync also run on the destination.

2–5 years experience

3. Your monitoring says a SnapMirror relationship is Snapmirrored, but the business says DR data is old. What do you check?

Why they ask this: They want to see you look beyond the state column.

How you might answer: I’d run snapmirror show -fields healthy,lag-time and snapmirror show -instance for the Unhealthy Reason. Usually updates are failing because of the network, a full destination or a missing schedule. I’d fix the cause, run a manual update and confirm lag drops.

4. Walk me through a planned DR test that doesn’t affect production.

Why they ask this: They want a safe, repeatable procedure.

How you might answer: On the DR cluster I quiesce and break the relationships, mount or map the volumes, bring up the application on DR hosts and test. Production keeps running the whole time.

At the end I unmount, run resync in the original direction, which discards the test writes, and confirm the relationship is Snapmirrored and healthy again.

Senior level

5. How would you decide the SnapMirror schedule for different applications?

Why they ask this: They want design thinking linking RPO, change rate and bandwidth.

How you might answer: I’d start from the RPO each business owner needs, then check the change rate and the WAN bandwidth to see if transfers can finish inside that schedule. Critical databases might get 5- or 15-minute schedules or SnapMirror Synchronous, while file shares are fine hourly.

I’d spread schedules so all relationships don’t start on the same minute.

6. After a real disaster you ran at DR for a week. How do you get back to the main site?

Why they ask this: They’re testing whether you understand reverse resync and failback planning.

How you might answer: Once the main site is back, I reverse the relationships so DR is the source and production is the destination, and resync, which sends only the changes since the last common snapshot. When it’s caught up, I plan a short outage, stop the application at DR, do a final update, break, and reverse again so production is the source.

Quick quiz

Q1. What type must the destination volume of a SnapMirror relationship be?

  1. RW
  2. DP
  3. LS
  4. TMP
Show answer

B — the destination is a data protection volume.

Q2. What does snapmirror initialize do?

  1. Deletes the relationship
  2. Sends the full baseline copy
  3. Makes the DR volume writable
  4. Peers the clusters
Show answer

B — initialize is the first full transfer.

Q3. After snapmirror break, what is the destination volume type?

  1. DP
  2. RW
  3. Offline
  4. Restricted
Show answer

B — break makes it read-write.

Q4. What happens to data written on the destination when you run resync in the original direction?

  1. It is copied back to the source
  2. It is kept in a snapshot forever
  3. It is discarded
  4. It is merged
Show answer

C — resync goes back to the newest common snapshot.

Q5. Which fields best show that DR is really current?

  1. state only
  2. healthy and lag-time
  3. type and used
  4. policy and schedule
Show answer

B — a relationship can be Snapmirrored and still unhealthy and old.

Quick recap

  • SnapMirror copies a volume to a DP volume on another cluster, then sends only changed blocks.
  • Create, initialize, update, break and resync all run on the destination.
  • Watch healthy and lag-time, not just Mirror State.
  • quiesce and break make DR writable; resync throws away DR-side changes.
  • Volume mirrors don’t copy LIFs, protocols or exports.

Next lesson

Lesson 40: SnapMirror vault (SnapVault) and unified replication → You’ll keep 30 daily and 52 weekly copies on the backup cluster with a vault policy and labels.

Further reading: ONTAP SnapMirror

Want to go deeper into ONTAP SnapMirror? Read NetApp’s ONTAP concepts guide for how SnapMirror, Snapshot copies and peering fit together. You can also see the full plan for this course on the NetApp ONTAP Storage Administration course page.

Scroll to Top

This website uses cookies

We use a few cookies to keep this site working. If you allow it, we also use Google Analytics to count visits so we can improve our lessons. You can accept all, deny the optional ones, or choose what to allow.