QoS limits for noisy neighbours

Every shared storage system eventually gets “the month-end problem”: one report job or one backup starts, and every other application on the same disks slows down. The DBA blames storage, the storage team blames the report, and nobody has numbers.

ONTAP gives you both the numbers and a fix. In this lesson you’ll split latency into layers to see where time goes, find the volume doing the damage, cap it with a QoS policy group, and learn why sometimes moving the volume is the better answer.

Where this lesson fits

Lesson 44 of 56 in NetApp ONTAP Storage Administration · Phase 3: Data protection and integrations · Before this: Lesson 43, backup integration · Next: Lesson 45, Active IQ Unified Manager

TimeYou needBy the end you can
45 minutesThe practice shell with svm1 and two data aggregatesRead qos statistics latency and performance, create and assign a QoS max policy, and explain min and adaptive QoS

What it is, in one line

ONTAP QoS (storage quality of service) puts a ceiling, or on all-flash systems a floor, on the IOPS or throughput of a volume, LUN or SVM, so one busy workload can’t starve its neighbours.

In Simple Words

One tap in a shared water tank

A building has one water tank and twenty flats. One family starts filling a swimming pool with a garden hose, and suddenly the taps in every other flat drop to a trickle.

The society doesn’t ban the pool; it fits a flow limiter on that family’s pipe. Their pool fills more slowly and everyone else gets normal pressure back, and if the pool is still too much, the society moves it to the other tank.

Engineer's View

How an engineer describes it

A QoS policy group holds a limit and is attached to workloads: volumes, LUNs, files or a whole SVM. -max-throughput sets a ceiling in IOPS, MB/s or both (for example 2000iops,100MB/s); requests above it are queued, which shows up as the QoS Max column in latency statistics. -min-throughput sets a floor that ONTAP tries to guarantee, and it’s meant for all-flash systems.

Adaptive QoS policy groups set expected and peak IOPS per TB, so the limit grows when the volume grows; ONTAP ships ready-made ones (extreme, performance, value) that suit service catalogues. By default a policy group’s limit is shared by all its workloads, so put one noisy volume per group unless you mean to share.

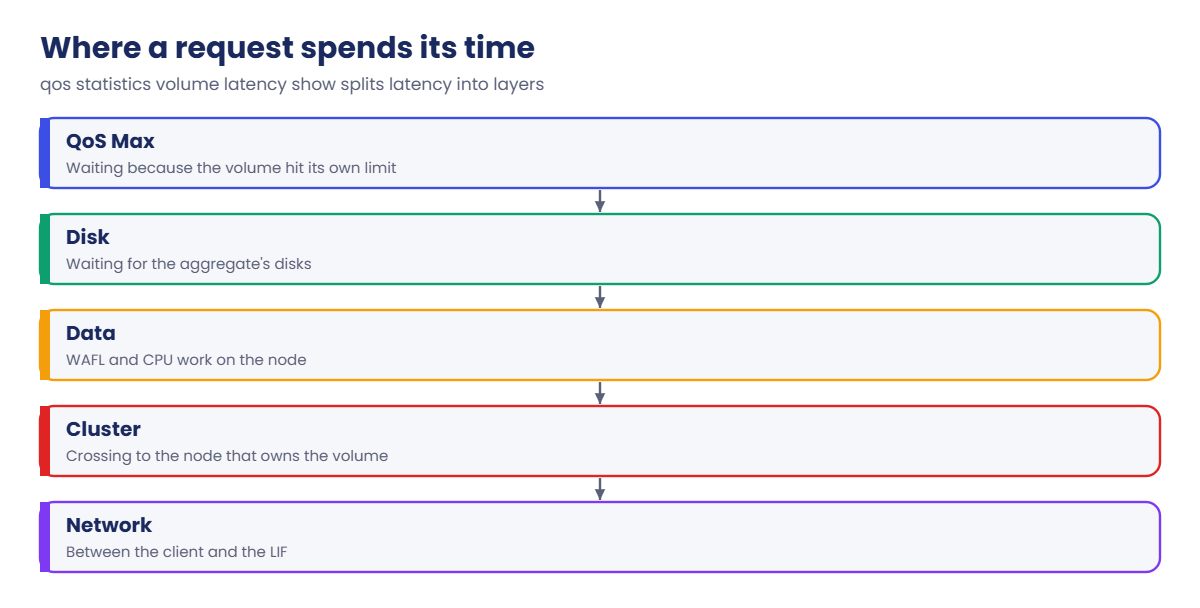
qos statistics volume latency show splits each volume’s latency into Network, Cluster, Data, Disk, QoS Max and more. The biggest column is where to look: high Disk means the aggregate is busy, high Cluster means traffic is crossing to another node, high QoS Max means a limit is working as designed.

How it works, step by step

1Measure before you limit

Run latency and performance statistics during the slow period. Latency shows which layer is slow; performance shows which volume is doing the most IOPS and MB/s.

2Confirm the noisy one

A neighbour is noisy when its IOPS jump at the same time other volumes’ Disk latency jumps on the same aggregate. Check it isn’t a background job such as a dedupe scan or a SnapMirror baseline first.

ONTAP QoS latency breakdown: network, cluster, data, disk and QoS Max

3Create a policy group and attach it

Pick a ceiling from what the workload really needs, agree it with its owner, create the group and attach it with volume modify -qos-policy-group.

4Watch both sides

The capped volume now shows QoS Max latency, which is expected. The neighbours’ Disk latency should drop; if it doesn’t, the aggregate is simply too busy and the limit alone won’t fix it.

ColumnHigh value means
NetworkClient side or LIF network problem
ClusterRequests crossing to another node (indirect access)
DataBusy node CPU or WAFL work
DiskAggregate disks are the bottleneck
QoS MaxThe workload is held back by its own limit
ONTAP QoS policy types compared: max, min and adaptive

5Fix the placement if needed

If capping isn’t enough, move the noisy volume to a less busy aggregate (Lesson 3’s volume move) and keep a sensible cap on it. Placement fixes the cause; QoS limits the damage.

In System Manager, edit a volume under Storage › Volumes and choose a Performance service level, or Custom to type IOPS and MB/s limits. Policies are listed under Storage › Storage VMs, select the SVM, Settings › QoS policies.
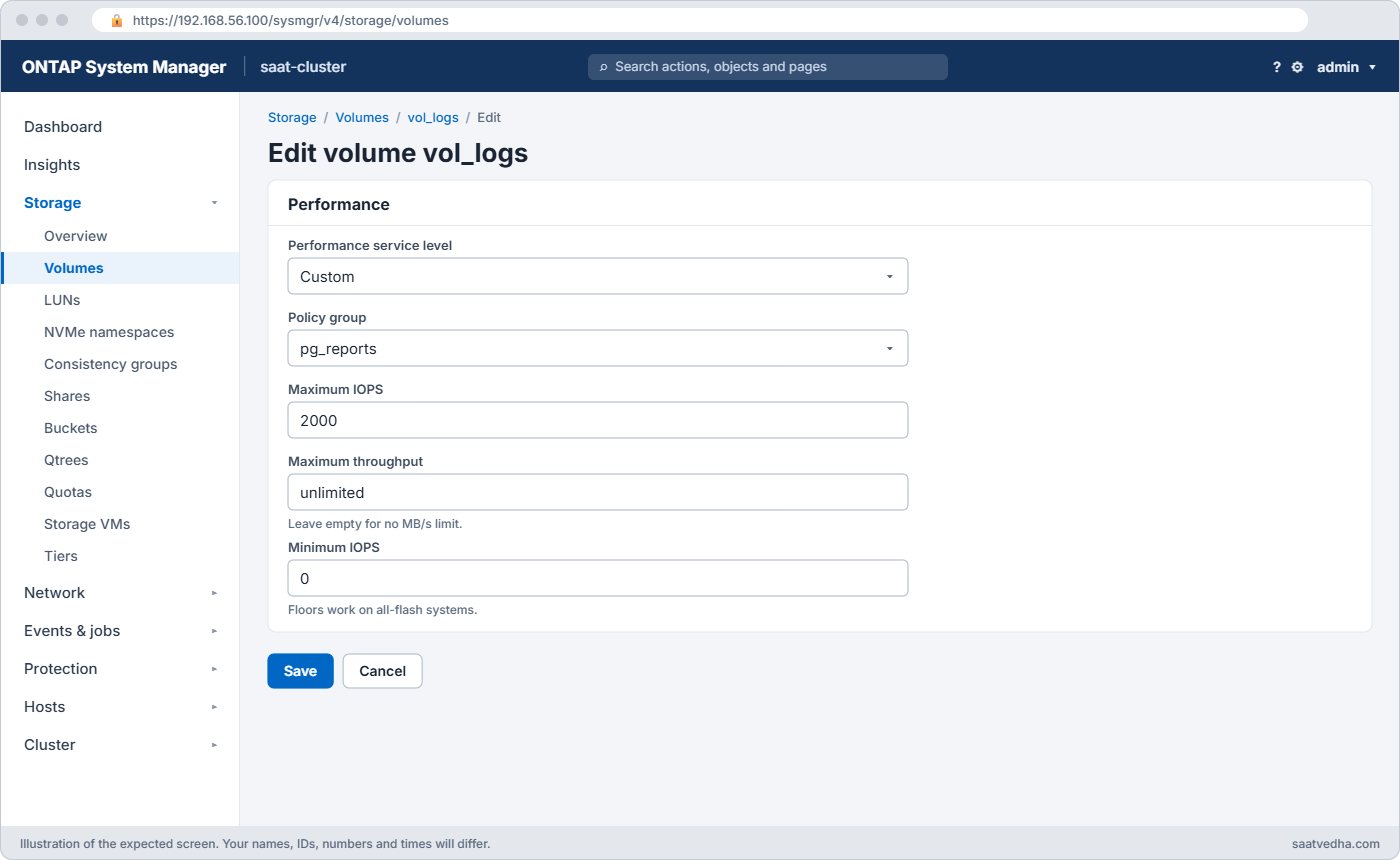
ONTAP QoS custom performance limit of 2000 IOPS on a volume in System Manager
System Manager: a custom QoS limit of 2000 IOPS on the volume.

Good to know: let ONTAP choose where a new volume goes

When you provision from System Manager, you usually don’t pick an aggregate. Balanced placement looks at the space and performance headroom of every local tier and places the new volume or LUN where it fits best.

For common applications such as databases or virtual servers, System Manager can also apply recommended settings for you, including a performance service level that sets QoS limits. Use it for routine requests, and use the CLI when you need exact control over the aggregate, the policy or the layout.

Hands-on lab: find and cap a noisy neighbour

Before you run any command, double-check it

Read every command twice before you press Enter. Check the target: the server name, the user, the disk or device name, the path and the sizes. These commands are for learning and were tested in our lab, not on your system. At work, run the read-only commands first, follow your change process, make sure a backup exists, and ask a second person to check anything that changes or deletes data. You run them at your own risk.

This lab uses the SaatVedha ONTAP practice shell, our own learning tool. It is not NetApp software: real ONTAP output looks like this but is not identical.

Start from the usual setup with svm1, aggr1_01 and aggr1_02. Your numbers will differ a little on each run; compare the patterns, not the exact values. Real ONTAP keeps printing statistics until you press Ctrl-C, while -iterations 1 prints one sample.

1Two volumes on one aggregate, one busy ERP

volume create -vserver svm1 -volume vol_erp -aggregate aggr1_01 -size 200g -junction-path /erp
volume create -vserver svm1 -volume vol_reports -aggregate aggr1_01 -size 200g -junction-path /reports
simctl load svm1 vol_erp 3000 40 0.5
qos statistics volume latency show -iterations 1

You should see something like this:

Workload            ID    Latency    Network    Cluster       Data       Disk    QoS Max    QoS Min      NVRAM      Cloud  FlexCache    SM Sync         VA     AVSCAN
--------------- ------ ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ----------
-total-              -    15.72ms    60.21us        0ms   150.53us    15.51ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_erp-wid2709   2709    15.72ms    60.21us        0ms   150.53us    15.51ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms

The ERP volume runs at about 15 ms, almost all of it in the Disk column, which is normal for SAS hard disks. Scroll the output sideways to see every column.

✅ Checkpoint: vol_erp shows about 15 ms, mostly Disk.

2The report job starts

simctl break noisy-neighbor svm1 vol_reports
qos statistics volume latency show -iterations 1
qos statistics volume performance show -iterations 1

You should see something like this:

Workload            ID    Latency    Network    Cluster       Data       Disk    QoS Max    QoS Min      NVRAM      Cloud  FlexCache    SM Sync         VA     AVSCAN
--------------- ------ ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ----------
-total-              -    50.66ms    59.46us        0ms   607.45us    50.00ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_reports-wid   9745    60.57ms    57.45us        0ms   586.98us    59.93ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_erp-wid2709   2709    40.76ms    61.46us        0ms   627.92us    40.07ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
saat-cluster::> qos statistics volume performance show -iterations 1
Workload            ID     IOPS       Throughput    Latency
--------------- ------ -------- ---------------- ----------
-total-              -    45904        897.56MB/s          -
vol_erp           2709     3079         41.06MB/s    40.85ms
vol_reports       9745    42824        856.50MB/s    60.20ms

ERP latency nearly tripled and the extra time is in Disk. The performance view shows why: vol_reports is pushing over 40,000 IOPS on the same aggregate.

✅ Checkpoint: You can name the noisy volume and the busy layer.

3Cap the noisy volume

qos policy-group create -policy-group pg_reports -vserver svm1 -max-throughput 2000iops
volume modify -vserver svm1 -volume vol_reports -qos-policy-group pg_reports
qos policy-group show
qos statistics volume latency show -iterations 1

You should see something like this:

Volume modify successful on volume vol_reports of Vserver svm1.
saat-cluster::> qos policy-group show
Name             Vserver     Class        Wklds Throughput
---------------- ----------- ------------ ----- ------------
pg_reports       svm1        user-defined 1     0-2000IOPS
saat-cluster::> qos statistics volume latency show -iterations 1
Workload            ID    Latency    Network    Cluster       Data       Disk    QoS Max    QoS Min      NVRAM      Cloud  FlexCache    SM Sync         VA     AVSCAN
--------------- ------ ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ----------
-total-              -   102.00ms    59.17us        0ms   147.92us    49.90ms    51.90ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_reports-wid   9745   164.42ms    57.93us        0ms   144.82us    60.42ms   103.79ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_erp-wid2709   2709    39.59ms    60.41us        0ms   151.02us    39.38ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms

The cap works: vol_reports now spends about 100 ms per request in QoS Max. But ERP is still near 40 ms, because even 2000 IOPS of random reads is a lot for eight SAS disks. The limit alone isn’t enough here.

✅ Checkpoint: vol_reports shows QoS Max latency; vol_erp is still slow.

4Move the reports volume to the other aggregate

volume move start -vserver svm1 -volume vol_reports -destination-aggregate aggr1_02
simctl tick 3
qos statistics volume latency show -iterations 1
qos statistics volume performance show -iterations 1

You should see something like this:

Workload            ID    Latency    Network    Cluster       Data       Disk    QoS Max    QoS Min      NVRAM      Cloud  FlexCache    SM Sync         VA     AVSCAN
--------------- ------ ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ---------- ----------
-total-              -    76.92ms    59.02us        0ms   147.55us    22.20ms    54.52ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_reports-wid   9746   138.91ms    60.86us        0ms   152.14us    29.66ms   109.04ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
vol_erp-wid2709   2709    14.93ms    57.18us        0ms   142.96us    14.73ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms        0ms
saat-cluster::> qos statistics volume performance show -iterations 1
Workload            ID     IOPS       Throughput    Latency
--------------- ------ -------- ---------------- ----------
-total-              -     4914         78.80MB/s          -
vol_erp           2709     2923         38.98MB/s    15.27ms
vol_reports       9746     1990         39.82MB/s   136.33ms

ERP is back to about 15 ms. The reports volume keeps its QoS cap on its new aggregate, so it can’t hurt whatever lives there either. Its workload ID changed because the volume moved.

✅ Checkpoint: vol_erp is back near 15 ms.

5Try an adaptive policy

qos adaptive-policy-group create -policy-group apg_db -vserver svm1 -expected-iops 2000IOPS/TB -peak-iops 4000IOPS/TB
qos adaptive-policy-group show

You should see this:

Name             Vserver    Wklds Expected IOPS  Peak IOPS
---------------- ---------- ----- -------------- ------------
apg_db           svm1       0     2000IOPS/TB    4000IOPS/TB

A 2 TB volume in this group could burst to 8000 IOPS, and if it grows to 4 TB the ceiling grows with it. That’s how service catalogues offer “gold” and “silver” storage without editing limits by hand.

✅ Checkpoint: apg_db shows 2000 and 4000 IOPS per TB.
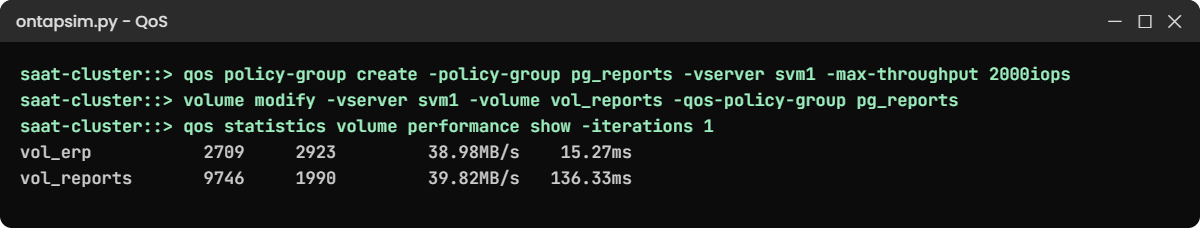
Practice shell output: ONTAP QoS policy group caps the noisy volume and latency is read per layer
After the cap, the reports volume waits in QoS Max, and once it moves to the other aggregate the ERP volume is back near 15 ms.

Break It, Then Fix It

Continue from the end of the lab.

Practice shell output: a QoS limit set too low makes the capped volume wait
At 500 IOPS the report job spends almost two seconds per request waiting on its own limit.

1Set the limit far too low

qos policy-group modify -policy-group pg_reports -max-throughput 500iops
qos statistics volume performance show -iterations 1

You’ll get something like this:

Workload            ID     IOPS       Throughput    Latency
--------------- ------ -------- ---------------- ----------
-total-              -     3373         48.31MB/s          -
vol_erp           5330     2872         38.30MB/s    28.05ms
vol_reports       5757      500         10.01MB/s  1828.63ms

The report job now waits almost two seconds per request and will run all night, yet nothing is broken: the limit is doing exactly what you asked. Agree limits with the workload’s owner, start generous, and lower them in steps while you watch both volumes. Put it back with -max-throughput 2000iops.

✅ Checkpoint: pg_reports is back at 2000 IOPS.

2Delete a policy group that is still in use

qos policy-group delete -policy-group pg_reports

You’ll get this:

Error: command failed: Policy group "pg_reports" is assigned to: vol_reports. Remove it from the workloads first.

Detach it first with volume modify -vserver svm1 -volume vol_reports -qos-policy-group none, then delete the group. Before you do, ask why it was added; a limit that disappears quietly brings the noisy neighbour back.

✅ Checkpoint: You know the order: detach, then delete.

This happened at work

The citizen portal that slowed down every night

A state e-services portal in Srinagar ran its application database and its analytics extracts on the same ONTAP aggregate. Every night at 9 p.m. citizens trying to download certificates got timeouts, and the database team kept asking for “faster storage”.

The storage engineer ran qos statistics volume latency show at 9:05 and saw database Disk latency jump from about 8 ms to over 60 ms. qos statistics volume performance show pointed at the analytics extract volume, which was reading at several hundred MB/s from the same disks.

She put a ceiling on the extract volume that night, and a week later moved it to a capacity aggregate on the other node. The extract job finished about forty minutes later than before, nobody minded, and the timeouts stopped. The team now reviews the top ten volumes by IOPS every month.

Common mistakes and troubleshooting

MistakeWhat happensDo this instead
Capping without measuringYou limit the wrong volume or the wrong amountRun latency and performance statistics during the slow period first
Putting many volumes in one policy group by accidentThey share one limit and starve each otherOne group per noisy workload, or adaptive groups
Treating QoS Max latency as a faultPeople raise tickets about a limit doing its jobExplain the column and agree limits with owners
Expecting a cap to fix an overloaded aggregateNeighbours stay slowMove volumes or add disks; use QoS to limit damage
Using min throughput on hard-disk systemsThe floor can’t be honouredUse floors on all-flash systems

Interview questions

Click a question to open it. Each one is written the way an interviewer would ask it. Under it you will see why they ask it and one way you could answer, in your own words.

Fresher level

1. What does QoS do in ONTAP, in simple words?

Why they ask this: They want to hear that it’s about protecting neighbours with limits.

How you might answer: It puts a speed limit, in IOPS or MB/s, on a volume, LUN or SVM so one busy workload can’t slow everyone else on the same disks. On all-flash systems it can also set a minimum to protect important workloads.

2. Users say a volume is slow. Which command shows where the time goes?

Why they ask this: They’re checking that you know the latency breakdown.

How you might answer: qos statistics volume latency show. It splits latency into Network, Cluster, Data, Disk, QoS Max and so on. The biggest column tells me whether it’s the disks, a node, the network or a QoS limit.

2–5 years experience

3. You capped a noisy volume but the other volumes are still slow. What next?

Why they ask this: They want to see you know the limits of QoS.

How you might answer: I’d check the aggregate is simply overloaded even with the cap, which shows as Disk latency staying high. Then I’d move the noisy volume, or the victims, to a less busy aggregate, or add capacity. QoS limits damage; placement fixes the cause.

4. What’s the difference between a QoS policy group and an adaptive QoS policy group?

Why they ask this: They want to know when each is useful.

How you might answer: A normal policy group has a fixed ceiling or floor. An adaptive group sets expected and peak IOPS per TB, so the limit grows as the volume grows, which suits service tiers in large environments.

Senior level

5. How would you design storage service tiers for internal customers using ONTAP?

Why they ask this: They want design thinking linking performance, cost and automation.

How you might answer: I’d define two or three tiers with adaptive QoS groups, say performance and value, mapped to aggregates on the right media. Provisioning automation would place each volume on a suitable aggregate and attach the tier’s policy.

I’d report each tier’s latency monthly and review the noisiest volumes, so tiers stay honest.

6. An application owner complains that your QoS limit is slowing them down. How do you handle it?

Why they ask this: They’re testing communication and judgement, not just commands.

How you might answer: I’d show them the numbers: their IOPS, their QoS Max latency, and what happened to neighbours before the limit. Then we’d agree what they really need, maybe a higher cap at night or a move to a faster tier, and I’d write the decision down so the limit isn’t a mystery later.

Quick quiz

Q1. Which latency column shows time spent waiting on a QoS limit?

  1. Disk
  2. Cluster
  3. QoS Max
  4. Network
Show answer

C — QoS Max is time queued because of the ceiling.

Q2. Which option sets a QoS ceiling?

  1. -min-throughput
  2. -max-throughput
  3. -expected-iops
  4. -ceiling
Show answer

B — -max-throughput sets the ceiling.

Q3. Where are QoS minimums (floors) meant to be used?

  1. Any system
  2. All-flash systems
  3. Only on FAS with HDD
  4. Only on SnapMirror destinations
Show answer

B — floors are for all-flash systems.

Q4. What does an adaptive QoS group scale with?

  1. Number of clients
  2. Volume size
  3. Time of day
  4. Number of snapshots
Show answer

B — limits are per TB.

Q5. What must you do before deleting a policy group in use?

  1. Reboot the node
  2. Detach it from its workloads
  3. Delete the volume
  4. Turn off QoS cluster-wide
Show answer

B — ONTAP refuses while workloads are assigned.

Quick recap

  • Measure first: latency by layer, then IOPS by volume.
  • A policy group with -max-throughput caps a noisy workload.
  • QoS Max latency on the capped volume is expected.
  • If the aggregate is still overloaded, move a volume.
  • Adaptive QoS scales limits with size; floors are for all-flash.

Next lesson

Lesson 45: Active IQ Unified Manager monitoring → You’ll see how a monitoring server watches capacity, performance and protection across clusters, and what to alert on.

Further reading: ONTAP QoS

Want to go deeper into ONTAP QoS? Read NetApp’s ONTAP concepts guide for how storage QoS, aggregates and volumes relate. You can also see the full plan for this course on the NetApp ONTAP Storage Administration course page.

Scroll to Top

This website uses cookies

We use a few cookies to keep this site working. If you allow it, we also use Google Analytics to count visits so we can improve our lessons. You can accept all, deny the optional ones, or choose what to allow.